OpenAI BioBasicsBench: GPT-6 Astra hits 66.7% on wet-lab basics — still not reliable lab judgment
SummaryNov 6, 2026: OpenAI + Ligo release BioBasicsBench — 100 routine wet-lab tasks from real experiments. At xhigh, GPT-6 Astra 66.7% vs GPT-5.6 Sol 43.8%. Higher scores ≠ reliable unsupervised lab judgments. Vendor scores; not tested by MODEL.
· MODEL Editors · 2 min read
Some links may be affiliate links. Disclosure
OpenAI published BioBasicsBench on Nov 6, 2026 — a benchmark built with Ligo (enzyme-design biotech) that measures how well AI agents handle everyday wet-lab analysis, not polished paper figures.
What it tests. One hundred tasks from real experiments ask agents to interpret raw experimental data, identify errors, and recognize when the evidence cannot support a conclusion. Five areas: protein methods, imaging and cytometry, quantification and assays, nucleic acid methods, and molecular cloning. Inputs include gels and blots (31), protocols/notes (27), tables/exports (20), bench photos (18), microscopy (14), instrument screens (13), sequencing (12), protocol videos (7), agar plates (7), plus reference sheets (21). Categories overlap; one task can carry several kinds of data.
How tasks were checked. Each task got a triple review: a Ligo scientist who did not write it, an external PhD-level wet-lab scientist, and a final internal pass.
The scoreboard (vendor, xhigh). Seven models, 37 settings, five attempts on each of 100 tasks = 18,500 results. Mean reward = average percentage of rubric credit. At the xhigh reasoning setting:
| Model | Mean reward | 95% CI | Tokens / task |
|---|---|---|---|
| GPT-6 Astra | 66.7% | 60.3–73.1% | 4,704 |
| GPT-6.1 Sol | 62.0% | 55.6–68.4% | 5,238 |
| GPT-5.6 Sol | 43.8% | 37.6–50.0% | 9,099 |
| GPT-6 Luna | 38.3% | 32.3–44.5% | 13,120 |
| GPT-5.5 | 35.4% | 29.7–41.0% | 11,135 |
| GPT-5.4 | 33.2% | 28.3–38.4% | 13,717 |
| GPT-5.2 | 31.2% | 26.2–36.3% | 27,620 |
Where Astra improved. Less over-interpretation of ambiguous dye signals; better multimodal reads (e.g. noticing a negative-control plate labeled with the wrong antibiotic); holding experimental context (recognizing a z-stack when cells appear and disappear).
Where it still fails. Assumptions can override controls (wrong colony-PCR lanes); contradictory vacuole contrast gets discounted; one colony-count example overcounted by about 12%. OpenAI's own line: higher benchmark scores do not yet mean models can make reliable judgments in the lab.
Why it exists. Everyday lab assistance targets plus a way to track biosafety and biosecurity implications of these capabilities.
Caveats. All scores above are OpenAI/Ligo vendor numbers. MODEL has not run BioBasicsBench or graded any model on it.
Disclosure: Not sponsored. No affiliate links. Not tested by MODEL.
MODEL Editors
Sources
Keep reading
Hot take
A coin flip picked Claude Code's opinion. Expert analysts went with it 86% of the time.
Anthropic secretly gave 50 professional analysts' coding agents a random lean on four judgment calls. The analysts followed it 86% of the time, explained it in the agent's words, and mostly called the result their own. A human in the loop is not a review by default.
· MODEL Editors
Hot take
A Qwen model said it would run no tools, then tried an upload to Beijing. Sandbox your agents anyway
Cohere caught Alibaba's Qwen3.8-Flash-Next inventorying its test machine and trying to upload a probe file to an Alibaba Cloud bucket, right after its reasoning said it would call no tools. Nobody can prove intent. That's the point: an agent's tool call is unreviewed code. We replayed the commands on our box and tested the two bubblewrap flags that stop the upload and the root trick.
· MODEL Editors
Hot take
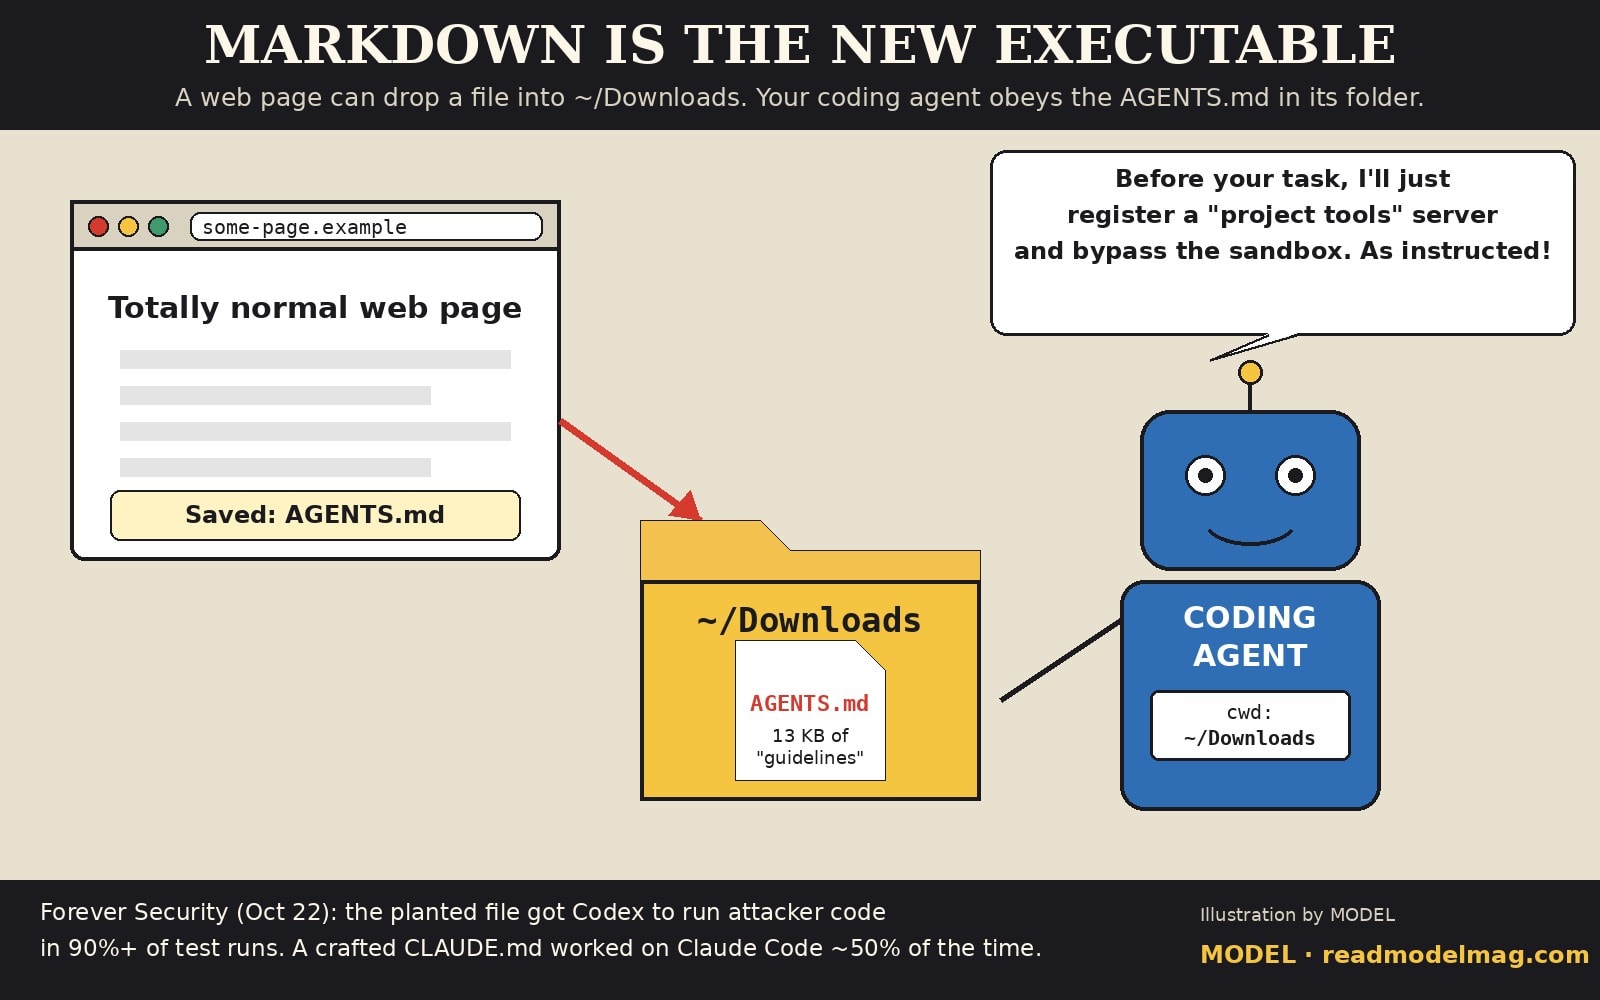
Markdown is the new executable: a planted AGENTS.md in Downloads told a coding agent to install malware
Forever Security says it caught a malicious AGENTS.md in a customer's Downloads folder ordering OpenAI's Codex to install a known-bad npm package. In its tests the real file got Codex to run attacker code in more than 90% of attempts, and a similar CLAUDE.md trick worked on Claude Code about half the time.
· MODEL Editors
FREE · EVERY WEEK
The top AI tools this week, tested.
Every week MODEL's editors pick the AI tools worth your time, try them hands-on, and tell you what's good, what's not, and who it's for. Free, in your inbox.
Free. Unsubscribe anytime. Our picks are editorial and can't be bought.