Mistral Large 4 is now open weights: a 1-trillion-parameter model you can download
SummaryMistral released the weights of Mistral Large 4, nicknamed Le Chonk, on October 29. It's a 1-trillion-parameter mixture-of-experts model with 49 billion parameters active per token, a 1M-token context and text-plus-image input, aimed at coding agents and defensive security work. The benchmark numbers are Mistral's own, and the official serving recipe uses 8 GPUs.
· MODEL Editors · 2 min read
Some links may be affiliate links. Disclosure
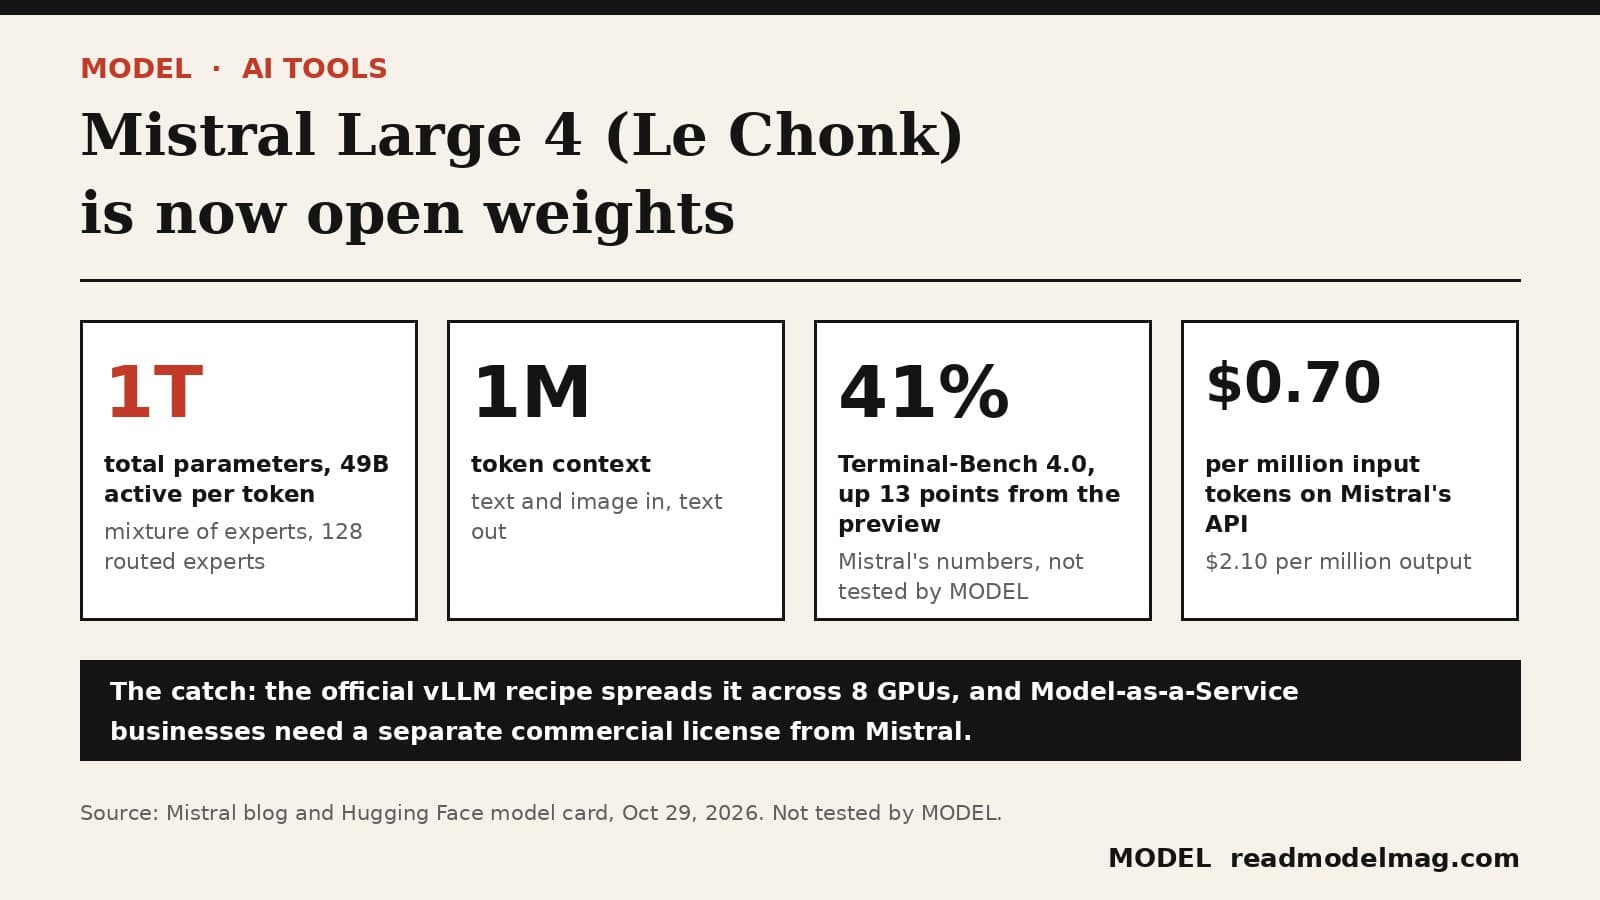
Mistral released the weights of Mistral Large 4 on October 29. The model, which Mistral calls Le Chonk, first appeared as an API-only public preview on October 6. Mistral says the version released today has had about three more weeks of reinforcement learning since then, mostly aimed at coding and defensive cybersecurity.
What it is. A mixture-of-experts model with about 1 trillion total parameters and 49 billion active per token (52 billion counting embedding and output layers): 128 routed experts, 4 active per token, plus 1 shared expert. It takes text and images in and writes text out, has a 1M-token context window, and supports function calling, JSON output and strict JSON schemas. Mistral says it was trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own data centers in Europe.
Three reasoning levels. You can set reasoning effort to low, medium or high (the default) per request, so the same model can do quick replies or long agent runs. Mistral says low replaces the old "none" mode.
Mistral's numbers. On Terminal-Bench 4.0, Mistral reports 41%, up 13 points from the preview, while using 30% fewer output tokens. On the Artificial Analysis Coding Agent Index it reports 48%, about tied with GLM-5.3 but using 47% fewer tokens per task on average. On Cognition's private FrontierCode 2.0 benchmark it reports 19.7%, the top score Mistral shows. For security work, Mistral reports 51% on the Artificial Analysis Cyber Index and a 96.6% average refusal rate on malicious cyber prompts. On the broader Artificial Analysis Intelligence Index v5 it scores 26; Mistral's own model card says the leading open models from China score higher there. MODEL has not run any of these benchmarks.
How to get it. Weights are on Hugging Face as mistralai/Mistral-Large-4-1T-A52B, with an NVFP4 quantized version for Blackwell GPUs. Mistral recommends vLLM and also documents SGLang, Transformers, llama.cpp, and fine-tuning with Axolotl, Unsloth and TRL. It's also on the Mistral API as mistral-large-4 at $0.70 per million input tokens, $0.07 per million cached input tokens and $2.10 per million output tokens, plus OpenRouter, Mistral's Vibe coding agent, NVIDIA-hosted endpoints and Microsoft Foundry. Mistral says its official demo Spaces on Hugging Face have a small shared free budget per visitor for the first week.
Who it's for: teams that want a large open model they can host themselves, especially for coding agents, security triage, or data that can't leave their own servers. If you just want to try it, the API or the demo Spaces are the easy way in.
The caveats. This is not a laptop model: the official vLLM and SGLang recipes spread it across 8 GPUs. The license is a modified MIT license that allows commercial use, but a business that runs a Model-as-a-Service offering needs a separate commercial license from Mistral. The benchmark results are Mistral's, and FrontierCode is a private benchmark. Mistral also says that, watching live traffic since the preview, it saw "a potential for uplift to conduct real attacks" and is changing its guardrails.
What MODEL did not test: we didn't download or run the weights, call the API, or check any benchmark or pricing claim ourselves.
Not sponsored. No affiliate links.
Sources
FREE · EVERY WEEK
The top AI tools this week, tested.
Every week MODEL's editors pick the AI tools worth your time, try them hands-on, and tell you what's good, what's not, and who it's for. Free, in your inbox.
Free. Unsubscribe anytime. Our picks are editorial and can't be bought.
Continue
Tool Update
OpenAI's Tibo: dots are getting GPT-6 Astra, GPT-6.1 Terra, and more
OpenAI's Tibo Sottiaux said the team is expanding the frontier models that power ChatGPT dots beyond today's Astra-only setup, adding GPT-6.1 Terra for speed and personality so more people can get a dot. Your dot will pick the model. It hasn't shipped yet.
· MODEL Editors
Hot Take
Hot take: sloppy AI code is a checking problem, not a model problem
Anthropic says Claude wrote the Rust port of its Messages API, starting with no Rust developers on the team, and that the safety net was shadow traffic, not line-by-line review. The same week, Veracode found about 4 in 10 AI coding tasks still produce code with a known vulnerability. Here is what was actually said, what the viral version gets wrong, and our take.
· MODEL Editors
Tool Update
Notion's week: its agent now makes Excel, Word, PowerPoint and PDF files, and edits say which agent did them
Notion's Halloween recap bundles four updates from Oct 27 to 30: an agent that builds real office files, speaker labels for Google Meet notes, bigger automatic offline downloads, and a 'Last edited by' label that names the agent or MCP client behind a change. Here is what each one does, and what Notion hasn't said.
· MODEL Editors