Benchmarks say Opus 5.5 is fine. Devs say it ate a crayon.
SummaryDevelopers on X and GitHub say Claude Opus 5.5 got 'nerfed' this week. Independent trackers show no sustained decline. The funny gap: dashboards say steady; agents keep retrying the same rejected fix.
· MODEL Editors · 2 min read
Some links may be affiliate links. Disclosure
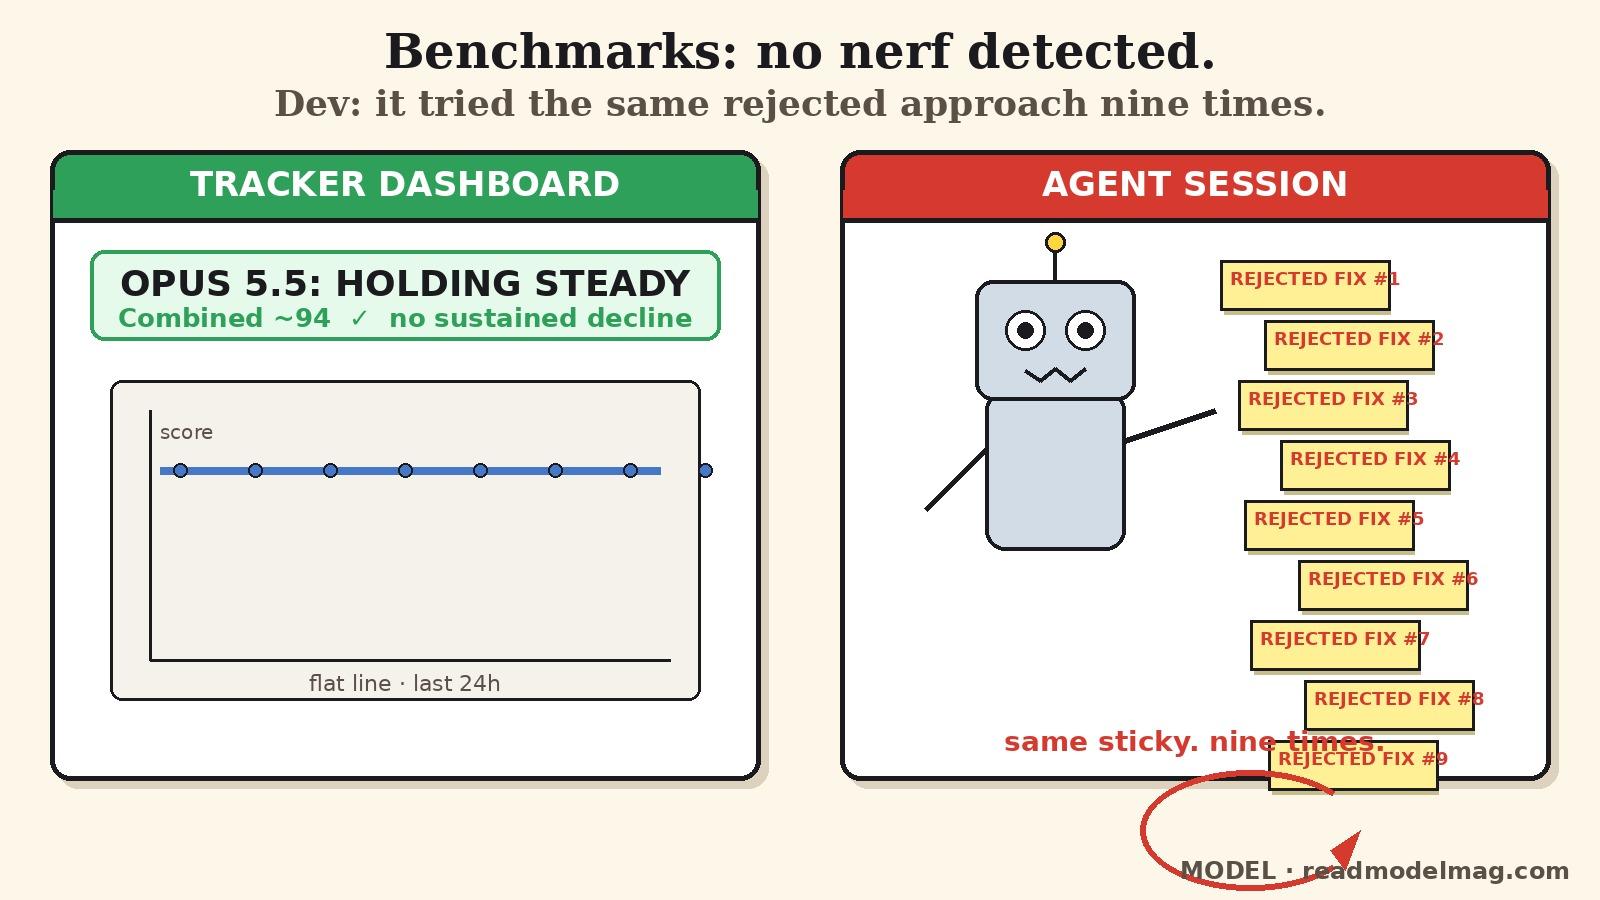
The vibes. This week developers on X and GitHub said Claude Opus 5.5 got worse — "nerfed." i10x counted roughly 2,700 posts on the topic in 24 hours. Data/AI engineer Irushi wrote that she "actually counted NINE times that it repeated the same rejected approach despite strict instructions." As of Nov 7, 2026, we found no public Anthropic reply on the complaints (i10x (opens in a new tab)).
What the trackers say. Independent boards built to catch post-launch drops are not calling one:
- AI Stupid Level (opens in a new tab) (as of Nov 7, 2026): Combined score about 94 ± 0.3, trend holding steady; "no sustained decline detected" on coding, reasoning, or tool use.
- LiveNerf (opens in a new tab) (day 45, Nov 7): three completed 10-day windows after launch week, no change detected on its frozen panel (window 3: +0.028 ± 0.023 vs launch week).
- BridgeBench NerfBench (opens in a new tab) (Oct 16 weekly post): Opus 5.5 at 105.8% of launch; every run cited in coverage stayed inside the 90–110% band; headline "No nerfs detected."
The strongest complaint log. In anthropics/claude-code#105112 (opens in a new tab), one power user scored their own Claude Code transcripts: corrected answers 5.2% of 5,738 before Oct 19 vs 25.4% of 900 after. Those are that author's measurements, not an Anthropic figure and not independently verified by MODEL. Their claim is not "lazy": tool calls and billed thinking held or rose; the failure mode is research done, then an answer that ignores what it just read.
A documented confounder (not a mid-life nerf). Anthropic's effort docs (opens in a new tab) say Claude Opus 5.5 and Claude Haiku 5.5 default to medium; earlier Opus models defaulted to high, so a request that omits effort runs one level lower than it did on Opus 5. That can make the model feel lighter without any silent weight change.
Anthropic has owned harness quality bugs before. In its April 23, 2026 Claude Code quality postmortem (opens in a new tab), the company traced weeks of "it got worse" reports to three product changes — a default effort cut, a caching bug that cleared prior thinking, and a verbosity prompt — not to intentional model degradation. All three were fixed by April 20 (v2.1.116). That history is context, not proof of a 2026-10 Opus 5.5 nerf.
Caveat (both can be true). Trackers mostly measure fixed or short API-style tasks. The loudest complaints are long, stateful agent sessions. A model can hold a frozen panel and still loop a rejected fix nine times in Claude Code. Do not read this as Anthropic confirming a nerf — they have not, publicly, as of Nov 7.
Disclosure: Not sponsored. No affiliate links. Not tested by MODEL. GitHub correction rates are the issue author's own logs.
MODEL Editors
Sources
- Claude Opus 5.5 benchmark & degradation tracker
AI Stupid Level
- livenerf README (day 45 update, Nov 7 2026)
GitHub
- BridgeBench NerfBench weekly results (Oct 16, 2026)
BridgeBench / teapawt
- [MODEL] Opus 5.5 since Oct 19: corrected answers 5.2% → 25.4% (#105112)
GitHub (anthropics/claude-code)
- Effort parameter documentation
Claude Docs
- An update on recent Claude Code quality reports (Apr 23, 2026)
Anthropic
- Claude Opus 5.5 'Nerf' Complaints: What Developers Report and What the Data Shows
i10x (Christopher Ort)
Keep reading
AI News
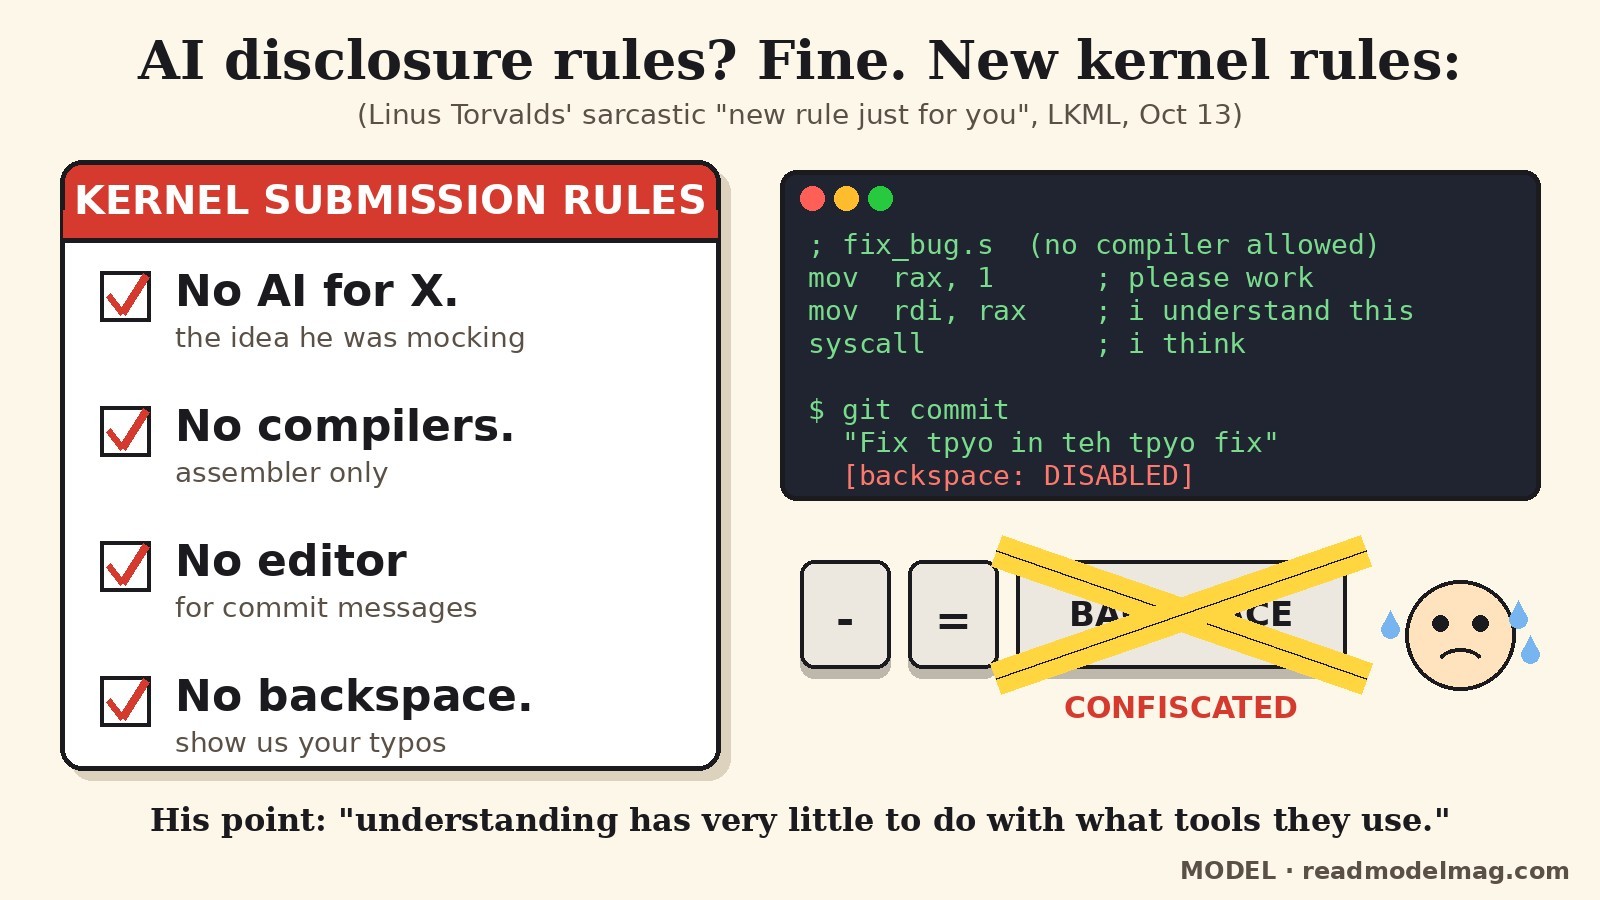
Torvalds' answer to AI disclosure rules: no compilers, no editor, no backspace
Oct 13, 2026: replying on the Linux kernel mailing list to a push to keep AI-use disclosure, Linus Torvalds proposed a sarcastic 'new rule' banning compilers and commit-message editors, then called such rules 'UTTERLY STUPID.' The quote is going around X again this week.
· MODEL Editors
AI News
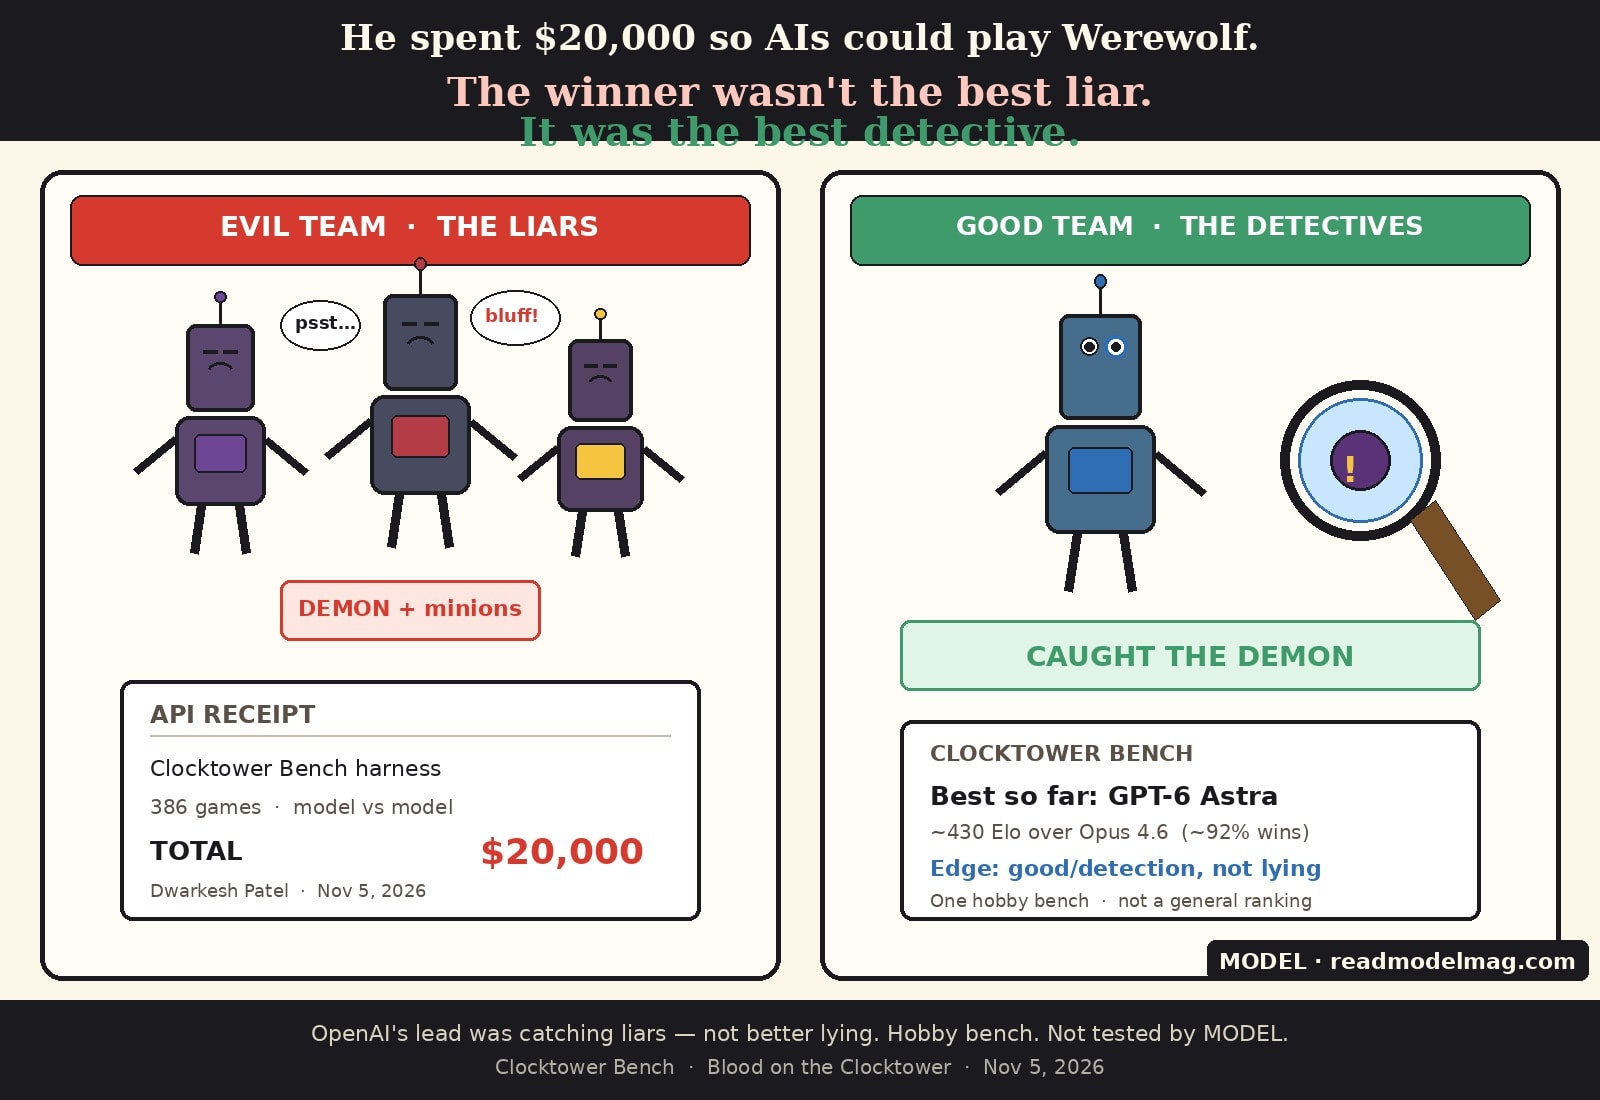
He spent $20,000 so AIs could play Werewolf
Dwarkesh Patel's Clocktower Bench (Nov 5) ran 386 Blood on the Clocktower games, model vs model. GPT-6 Astra leads Claude Opus 4.6 by ~430 Elo (~92% wins). The edge is detection, not better lying.
· MODEL Editors
AI News
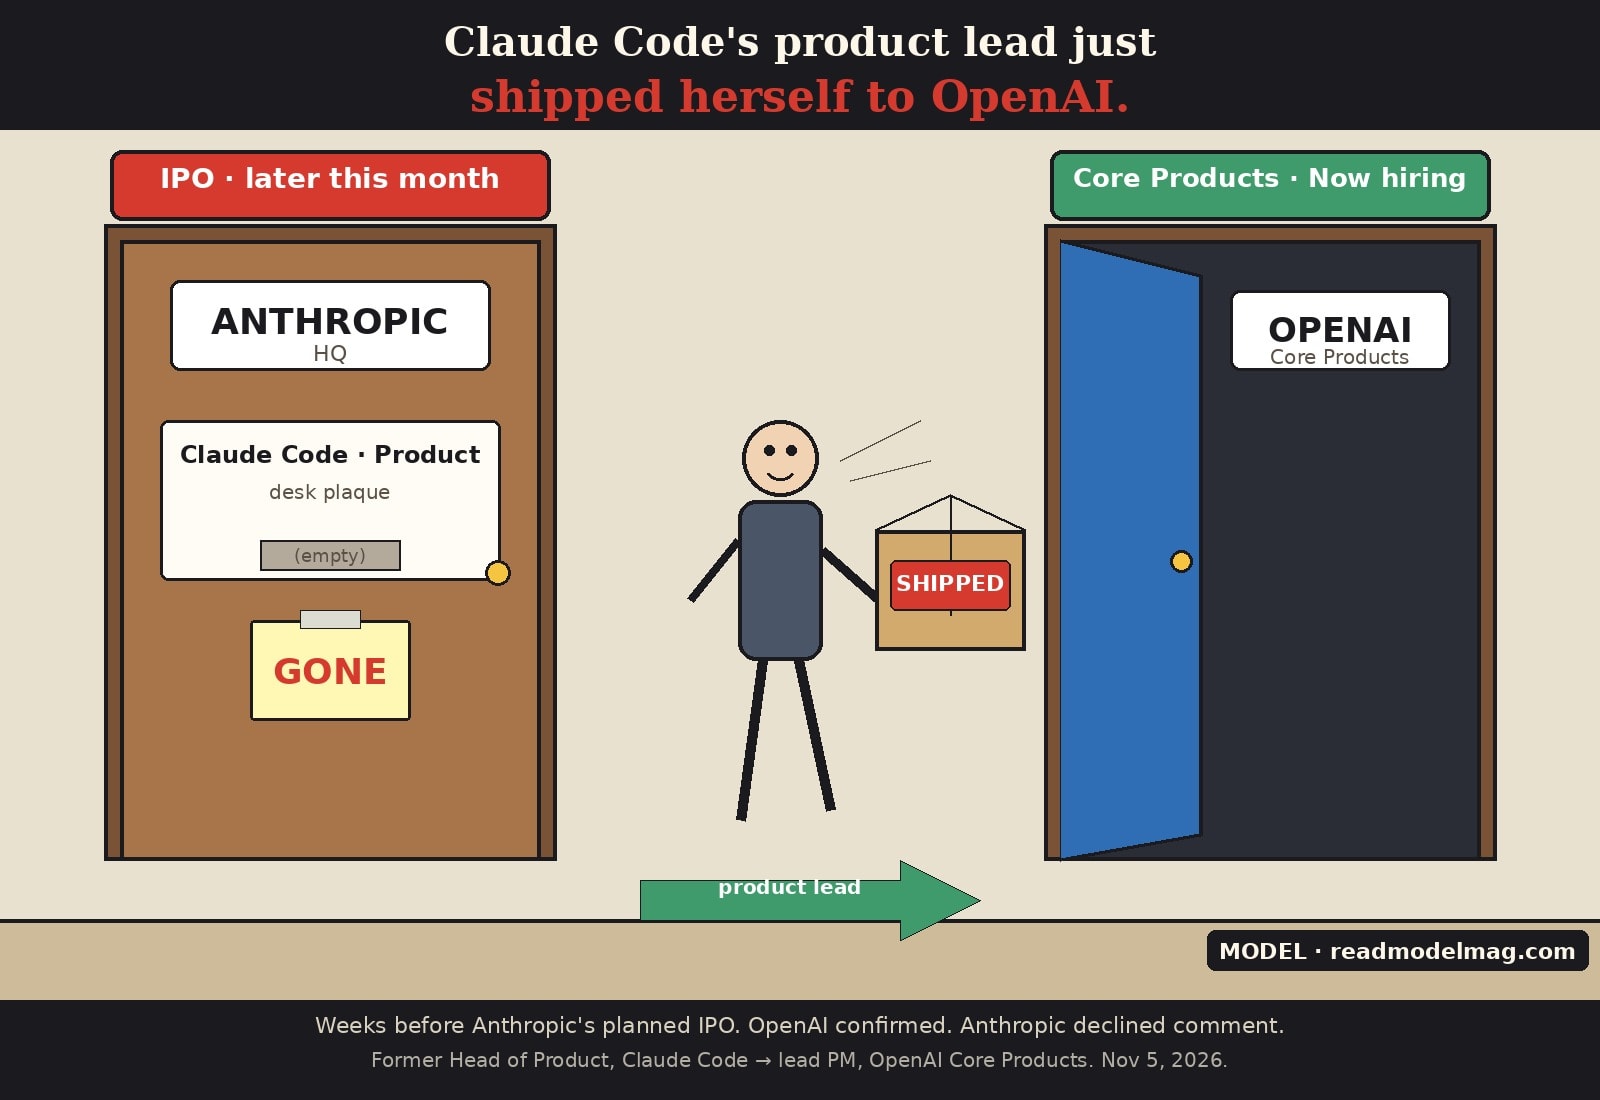
Claude Code's product lead just shipped herself to OpenAI
Cat Wu (@_catwu), former Head of Product for Claude Code (and Cowork) at Anthropic, is joining OpenAI to lead product management for Core Products — weeks before Anthropic's planned IPO. OpenAI confirmed to Business Insider; Anthropic declined comment.
· MODEL Editors
FREE · EVERY WEEK
The top AI tools this week, tested.
Every week MODEL's editors pick the AI tools worth your time, try them hands-on, and tell you what's good, what's not, and who it's for. Free, in your inbox.
Free. Unsubscribe anytime. Our picks are editorial and can't be bought.