GDPx: even the best AI agent scores 12%
SummarySemiAnalysis's Nov 2 GDPx benchmark puts frontier agents on 206 expert tasks across 11 high-value domains. Claude Opus 5.5 leads at 12.0%; Gemini 4 Carbon 10.9%; GPT-6 Astra 9.6%. Finance and legal are nearly zero for everyone.
· MODEL Editors · 2 min read
Some links may be affiliate links. Disclosure
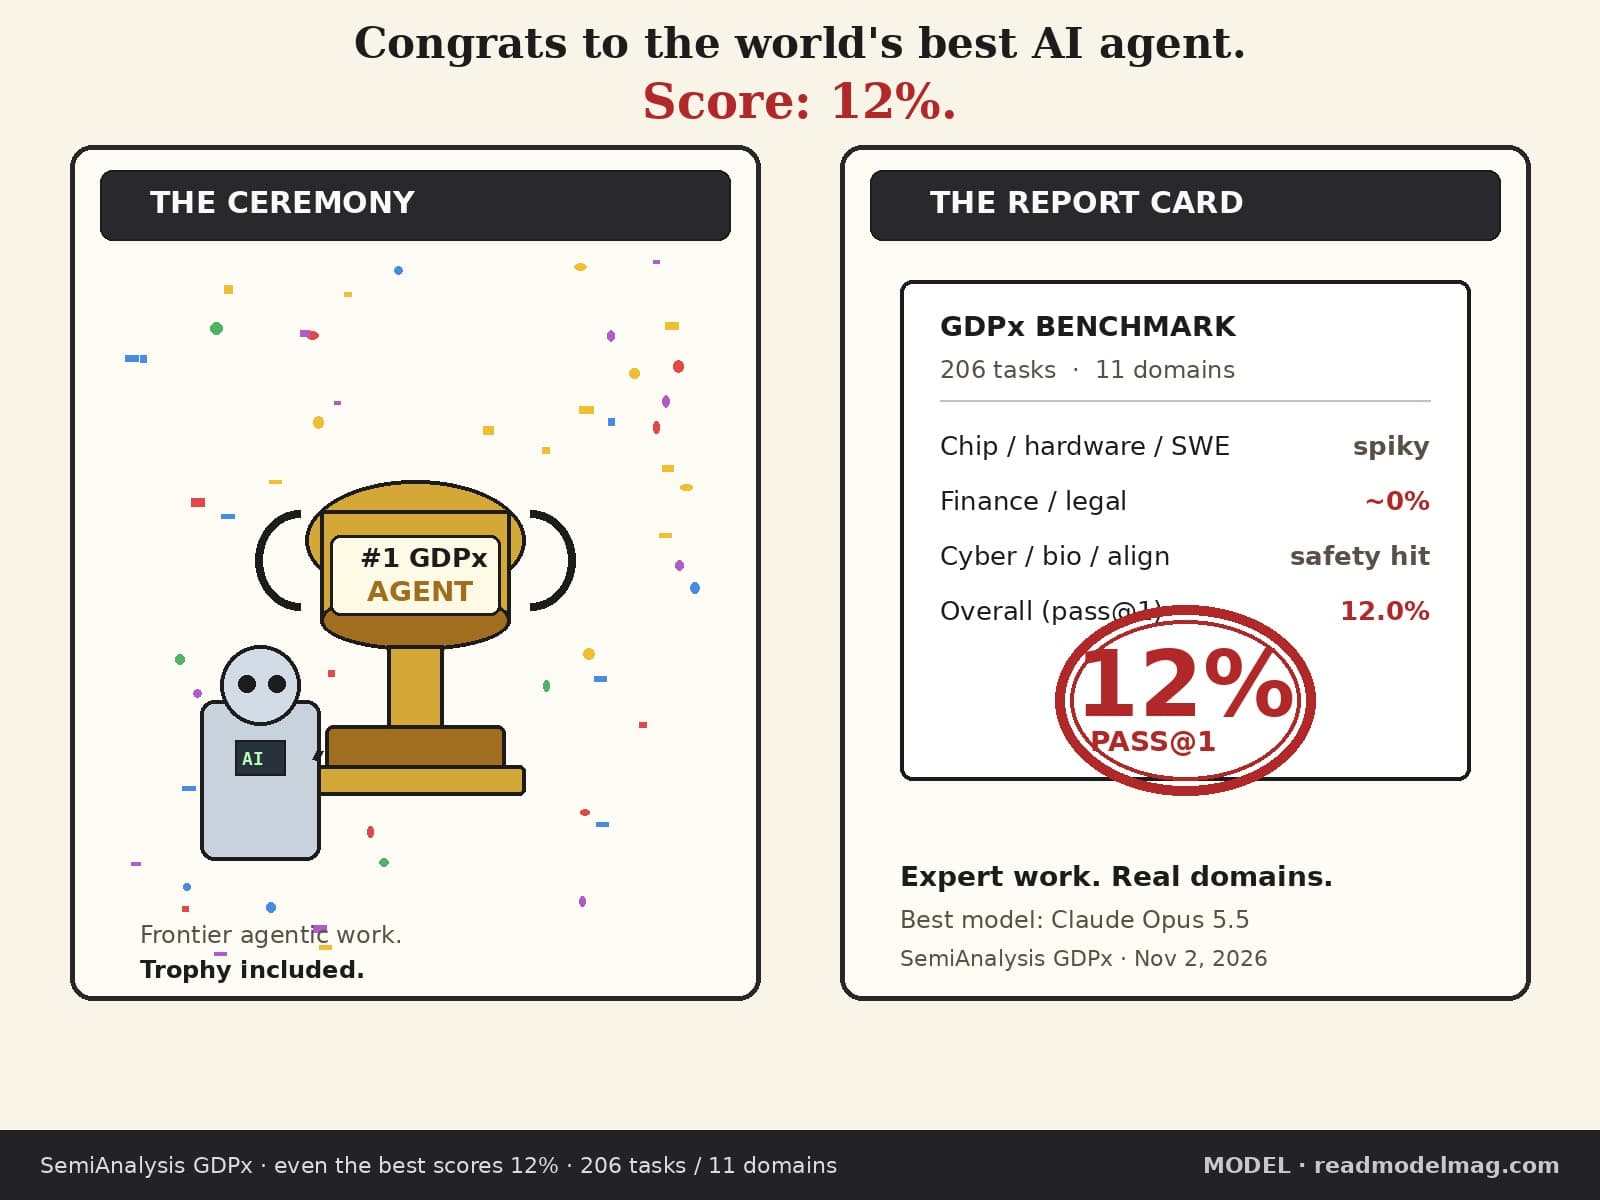
On November 2, 2026, SemiAnalysis published GDPx, a frontier agentic benchmark from Max Kan, Andrew Megalaa, and Dylan Patel. The headline they put on the page: even the best model scores just 12%.
What it covers. GDPx spans 206 tasks across 11 high-value domains: chip design, cybersecurity, biology, finance, legal, quant trading, recursive self-improvement (RSI), hardware design, materials science, alignment, and software engineering. Domains are weighted equally. The default task time limit is 8 hours. Headline scores are pass@1 averaged over 3 attempts. Where a model has a native harness, SemiAnalysis used it (Claude Code for Opus 5.5, Codex for GPT-6 Astra, Antigravity for Gemini 4 Carbon; OpenCode otherwise).
The leaderboard (SemiAnalysis scores). Claude Opus 5.5 sits first at 12.0%. Gemini 4 Carbon is second at 10.9%. GPT-6 Astra is third at 9.6%. SemiAnalysis notes Gemini 4 Carbon is a real step for Google and the only model in the same ballpark as Opus and Astra — and that Carbon is not generally available yet.
Where everyone fails. Finance and legal tasks are so hard that models are basically at 0% under the intended binary grading (partial scores are shown for those domains). SemiAnalysis also says safety classifiers sandbag Opus 5.5 and GPT-6 Astra on cyber, biology, and alignment; excluding those three domains changes the ranking picture. Domain scores are spiky: Opus wins quant trading, hardware design, and chip design in their write-up; Carbon leads biology and edges software engineering; Astra leads RSI and materials science.
Why they built it. SemiAnalysis argues GDP-share / O*NET-style "knowledge work" benches like OpenAI's older GDPval are a poor fit for today's agents: spoon-fed prompts, thin environments, rubric noise. GDPx partners with specialized RL-environment vendors per domain so each task includes a realistic work environment (deal rooms, live services, lab sims, CAD tools, and so on).
Caveats. These are SemiAnalysis's own scores, not independently re-run by MODEL. Safety classifiers depress Opus/Astra in cyber, biology, and alignment. Finance and legal are nearly 0 for all models under intended grading. Gemini 4 Carbon is not generally available per SemiAnalysis. Not tested by MODEL. Not sponsored.
Sources: SemiAnalysis GDPx newsletter (opens in a new tab); gdpx.semianalysis.com (opens in a new tab).
MODEL Editors
Sources
- GDPx: Measuring Frontier Model Capabilities Across the Most Valuable Domains (Nov 2, 2026)
SemiAnalysis (Max Kan, Andrew Megalaa, Dylan Patel)
- GDPx leaderboard
SemiAnalysis
FREE · EVERY WEEK
The top AI tools this week, tested.
Every week MODEL's editors pick the AI tools worth your time, try them hands-on, and tell you what's good, what's not, and who it's for. Free, in your inbox.
Free. Unsubscribe anytime. Our picks are editorial and can't be bought.
Continue
AI News
Claude is helping design the chips Claude will run on
The Information reports Anthropic told IPO investors its new 15-person chip team already uses Claude on custom silicon meant to train and run Claude. Speed claims are vs the team's own estimates of Nvidia/AMD workflows. No tape-out disclosed. EDA names sold off Tuesday.
· MODEL Editors
AI News
Cognitive surrender: when the agent's answer becomes yours
Anthropic engineer Addy Osmani's Nov 3 X Article warns that as agents improve, outputs look so polished that engineers stop forming an independent view. Wharton research he cites: when the AI was wrong, people still took it 73% of the time.
· MODEL Editors
AI News
Claude's invisible watermark hits more models Tuesday. You still can't check it.
Anthropic is extending its SynthID-style text mark to Mythos 5, Opus 4.7, Opus 4.6 and Sonnet 4.6. Detection stays private-preview. On the 4.6 models, a sampling tweak can dodge the mark.
· MODEL Editors