Sarvam's new 105B checkpoint targets cheap chat agents
SummarySarvam AI released Sarvam-105B-1711, an open-weight update built for customer support, voice agents and tool calls in Indian languages. Its own benchmarks put it level with Gemini 3.5 Flash-Lite at a lower price.
· MODEL Editors · 2 min read
Some links may be affiliate links. Disclosure
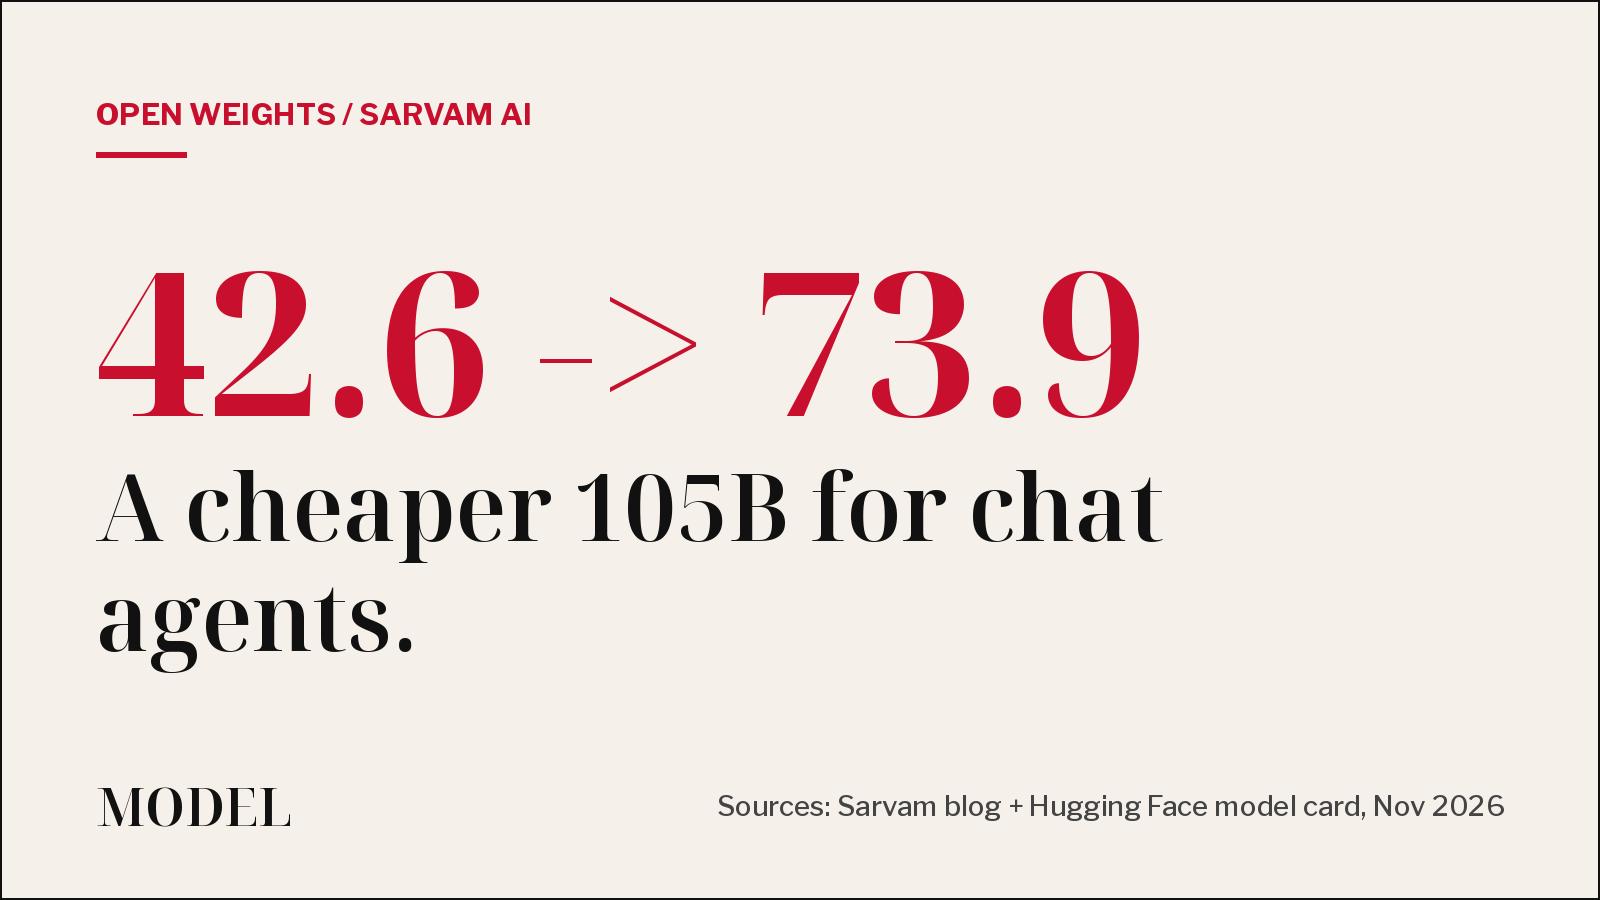
Indian AI lab Sarvam AI released Sarvam-105B-1711 (opens in a new tab) on Nov. 22, 2026. It is a new checkpoint of the Sarvam 105B model it open-sourced in February, post-trained for the jobs most chat agents do all day: follow a long system prompt, call the right tool, and answer in Indian languages.
What it is. A 105B-parameter mixture-of-experts model with 10.3B active parameters, per the Hugging Face model card (opens in a new tab). Sarvam calls it a "Flash-Lite" class model and pitches it for customer support, voice agents and agentic tasks. The weights are Apache 2.0: a 65 GB NVFP4 build (the one Sarvam serves in production) and BF16 weights for fine-tuning.
The numbers, from Sarvam's own runs.
- Average across eight conversational-agent benchmarks: 42.6 for the February model, 73.9 now. Gemini 3.5 Flash-Lite scores 74.0 and Gemma 4 31B 73.0 on the same set.
- IFBench (instruction following): 32.5 to 82.5. Tau2 (tool use in customer-service chats): 46.2 to 85.5. Sarvam's Indic suite: 30.1 to 79.1.
- Blended price: about $0.15 per million tokens, down from $0.44, by Sarvam's math (3 input : 1 output, at Rs 90 per dollar). Sarvam lists Gemini 3.5 Flash-Lite at $0.85 on the same basis.
Price and access. On Sarvam Token Factory it costs Rs 10 per million input tokens and Rs 25 per million output tokens. The docs (opens in a new tab) call that introductory pricing through the end of 2026. The existing sarvam-105b model ID now runs on the new weights with no code changes, with a 128K-token context window (32K for sarvam-105b-conversations). Sarvam says the NVFP4 build fits on one RTX PRO 6000 Blackwell GPU, and vLLM and NeMo RL support are already merged.
Who it's for. Teams building support bots or voice agents that need Indian languages or data kept in India, and anyone who wants open weights they can host themselves.
The catch. Every benchmark here is Sarvam's own evaluation, not an independent one. It is not the best at everything in its class: Gemini 3.5 Flash-Lite beats it on GDPval-S (73.0 vs 66.9), and Qwen3.8 27B has a slightly higher eight-benchmark average (74.6) at a higher price. It scores 12.3 on Humanity's Last Exam without tools, well behind GPT-6 Luna's 30.6 in Sarvam's table. The low price is introductory. And Sarvam's single-GPU setup is a 96 GB RTX PRO 6000 Blackwell workstation card, not a laptop.
Our take. For high-volume chat work in Indian languages, this is a serious, cheap open option. Run it on your own tasks before trusting the vendor chart.
From Sarvam AI's blog, Hugging Face model card and docs, read Nov. 22, 2026. MODEL did not run these tests. Not sponsored. -- MODEL Editors
Get three tested tools every Friday
Free, weekly. Unsubscribe anytime.
Sources
- Introducing Sarvam-105B-1711
Sarvam AI blog (Nov. 22, 2026)
- sarvamai/sarvam-105b-1711 model card
Hugging Face
- Sarvam-105B (Token Factory model docs)
Sarvam docs
Keep reading
Builder tip
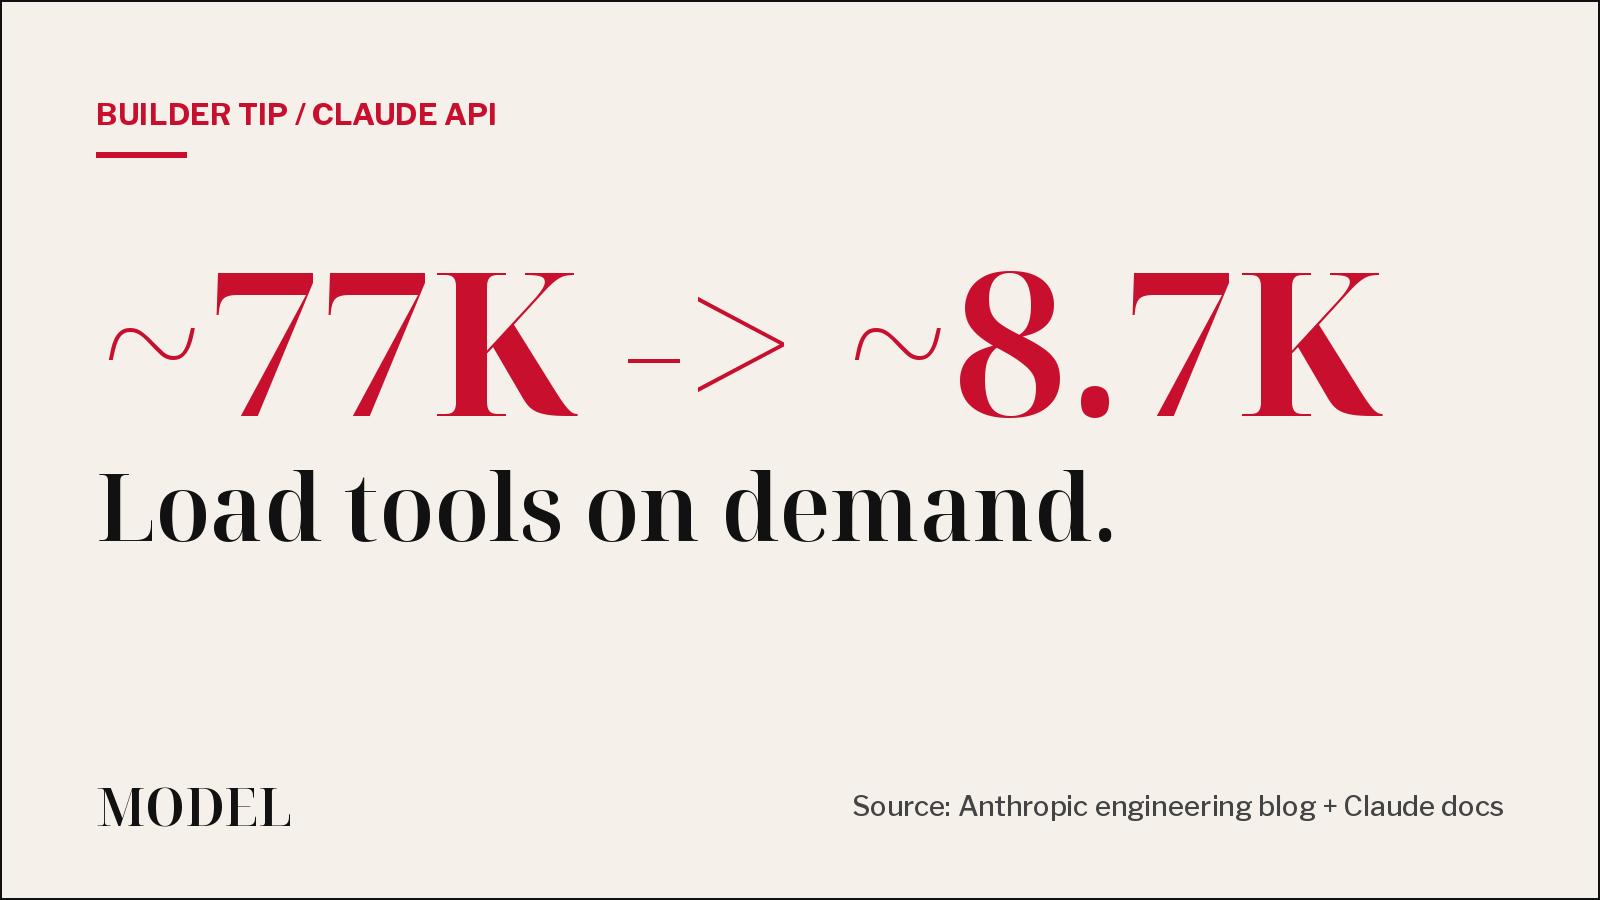
Your agent doesn't need all 58 tools in context. Defer them.
A thread calling Anthropic's tool-use write-up a new paper is going around X this weekend. It is a year old, and the advice still holds: mark most tools defer_loading and let Claude search for the few it needs.
· MODEL Editors
Hot take
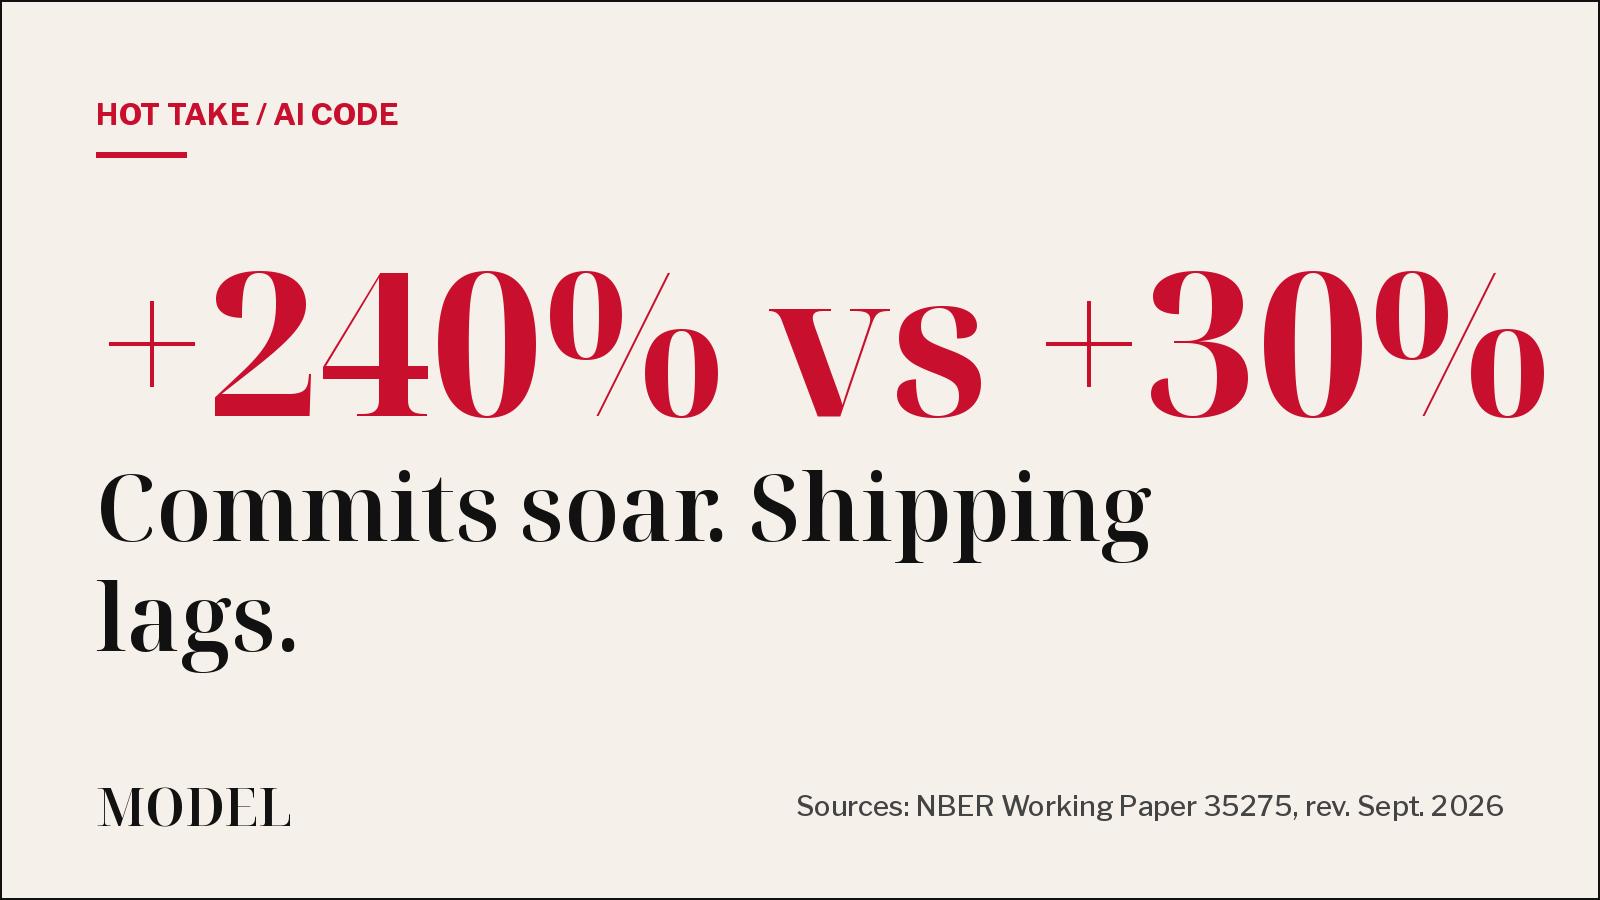
AI agents more than tripled commits. Releases rose 30%.
An NBER working paper that tracked more than 500,000 GitHub developers finds AI coding tools add huge amounts of code, but much less of it ships. It is circulating again this weekend. Our take: the bottleneck is now review, not typing.
· MODEL Editors
Tools
Claude Code's Code Mode reaches the stable channel: what it does, and the catch
Code Mode has Claude write JavaScript that runs several tool calls in one step, including background scripts for up to two hours. A week after launch, the stable channel has caught up.
· MODEL Editors
The test
AWS Emulator 1.0.523, tested: a local AWS that refused what it should, and one old-CLI call that went to the real thing
We ran AWS's free local emulator on Linux with no AWS account and no real keys. S3, SQS and DynamoDB worked, it was up in 0.23 seconds, and it enforced the three permission checks we tried. The catch: AWS CLI v1 sent one SQS call to the real AWS endpoint.
· MODEL Editors
FREE · EVERY WEEK
The top AI tools this week, tested.
Every week MODEL's editors pick the AI tools worth your time, try them hands-on, and tell you what's good, what's not, and who it's for. Free, in your inbox.
Free. Unsubscribe anytime. Our picks are editorial and can't be bought.